Our paper “OpenDesc: From Static NIC Descriptors to Evolvable Metadata Interfaces” will be presented today at HotNets’25.
In OpenDesc, we propose to use P4 as an interface to define packet descriptors. OpenDesc enables to expose NIC capabilities and match them with application intents. We propose a prototype compiler to generate accessors that can directly extract metadata from a negotiated NIC descriptor without the need for intermediate data structures like sk_buff, xdp_sock, rte_mbuf & cie.
Our latest paper with Louis Navarre, Quentin de Coninck, Tom Barbette and Olivier Bonaventure has recently appeared in SIGCOMM CCR!
In short: Flexicast QUIC brings multicast back to the Internet by blending it with unicast, all within QUIC. It offers scalability where multicast works, and robustness where it doesn’t — making it a practical transport for the next generation of large-scale applications.
When distributing live video, software updates, or cloud gaming streams, today’s Internet almost exclusively relies on unicast: each receiver gets its own copy of the data. This is simple and robust but highly inefficient, especially when thousands of receivers consume the same content. The cost is felt both at the sender — which must generate and encrypt per-receiver packets — and in the network, which carries redundant traffic.
Multicast was designed decades ago to solve exactly this problem: a source transmits once, and routers replicate packets along a multicast tree. But despite its promise, multicast never became mainstream on the global Internet. It is difficult to deploy across ISPs, hard to monetize, and fragile — applications always need to fall back to unicast anyway. Most content providers gave up and built massive unicast infrastructures instead.
With the wide deployment of QUIC, a modern transport protocol running above UDP, there is a chance to revisit multicast — not at the IP layer, but directly at the transport layer. This is where Flexicast QUIC comes in.
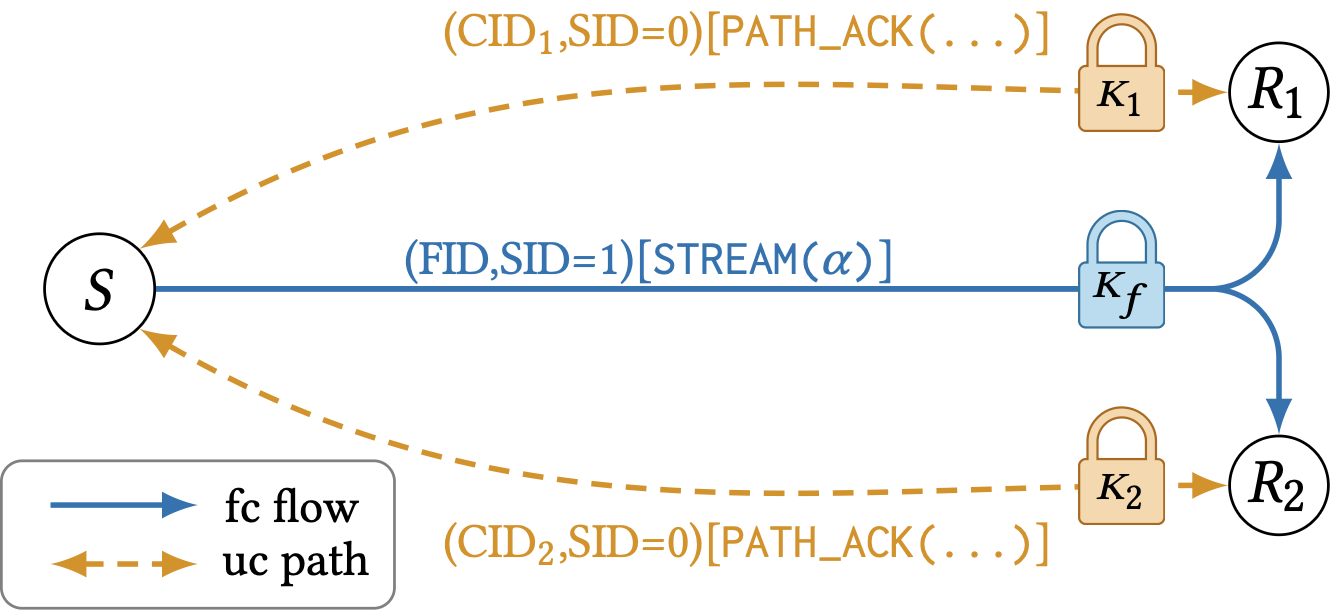
FlexiCast uses a multicast stream shared between users, and individual unicast streams to send feedback or act as a fallback. The feedback is used to send more FEC frame to compensate loss, and if the client can’t keep up, use unicast as a fallback.
The Idea of Flexicast QUIC
Flexicast QUIC, presented in our SIGCOMM CCR 2025 paper, extends Multipath QUIC to combine the efficiency of multicast with the reliability of unicast. The idea is to make multicast flexible:
Each receiver gets a unicast QUIC path for control and fallback.
The sender also establishes a flexicast flow: a shared, unidirectional path encrypted with a common key and intended for all receivers.
If multicast routing is available, this flow is carried efficiently through the network. If not, the sender can still replicate the packets itself and deliver them over unicast.
Receivers can join or leave the flexicast flow at any time. If multicast fails for one receiver, it automatically falls back to unicast — without affecting others. All this happens within the same QUIC connection, so applications don’t need to juggle two protocols.
Key Design Points
Flexicast QUIC builds on QUIC’s extensible design:
Per-path keys: unlike regular Multipath QUIC, each unicast path and the flexicast flow use distinct encryption keys.
Reliability: acknowledgments are sent over unicast paths, aggregated at the sender to avoid the classic ack implosion problem.
Congestion control: the sender maintains per-receiver congestion states. If one receiver drags the group down, it can be removed from the flexicast flow and served over unicast.
Implementation and Results
We implemented Flexicast QUIC in Cloudflare’s quiche library (Rust), adding ~10,000 lines of code and 5,000 lines of tests. The evaluation was run on CloudLab and emulated networks.
FlexiCast can scale much better than pure QUIC delivery
Scalability
Unicast QUIC: saturates at ~200 receivers (~20 Gbps). CPU is the bottleneck, as every packet must be encrypted per receiver.
Flexicast QUIC: supports 1000 receivers and delivers >80 Gbps, over 4× higher throughput than unicast QUIC, with acceptable CPU usage.
With a small acknowledgment delay (5 ms), Flexicast QUIC perfectly matches the ideal UDP baseline.
Even without multicast in the network, Flexicast QUIC still helps: the sender can replicate encrypted packets using sendmmsg, which is far cheaper than generating per-receiver packets.
Robustness
We tested Flexicast QUIC with a 5 Mbps live video stream under failing multicast trees. Some receivers randomly lost multicast connectivity, forcing fallback to unicast. Results:
Other receivers were unaffected.
Video quality stayed excellent (SSIM > 0.99 for 99.4% of frames).
Latency remained low, with only small tail increases during recovery.
This shows Flexicast QUIC provides seamless continuity even when multicast is unreliable.
Why It Matters
Flexicast QUIC makes multicast practical again:
Efficient: one packet can serve thousands of receivers.
Robust: unicast fallback is built-in, so failures don’t break the stream.
Practical: works today, even without multicast routers.
Deployable: it’s just QUIC — already used by major Internet services.
This makes it promising for content delivery networks, software updates, and live streaming at scale.
What’s Next?
Our future work will explore:
Forward Erasure Correction to improve reliability.
Smarter flow control for heterogeneous receivers.
Source authentication to defend against spoofed multicast traffic.
Multiple flexicast flows (e.g., different video bitrates).
I’m happy to share the exciting news that my project for the Incentive Grant for Scientific research (MIS) from our national fund for 470K€ (one PhD, one post-doc and equipment) was accepted, while a PhD student of our team, Clément Delzotti got his 4-year PhD funded by FNRS FRIA too!
The MIS project “DHNET: The Disaggregated Host Networking paradigm to enable particle-to-particle streams” is a more fundamental project looking beyond the current design of the Internet, to enable more efficient communications. The Internet is built around the idea monolithic computers are communicating. Each computer gets an address, and communicate together as a whole. As physician refined the model of atoms in particles, the Internet needs to be redesigned to look inside computers. Components, particles, like GPU, CPU caches, TPUs, network interfaces need to communicate directly together as computers are not monolithic devices anymore, but an interconnect of many components and memory domains. Why would a transfer, say a picture generated by a cloud gaming GPU go through a CPU, a proxy, a load balancer while it could be sent through a direct path to the consumer’s screen? In practice we will use the newfound programmability of networks with programmable switches and SmartNICs to direct the data to the right particle.
The FRIA grant obtained by Clément Delzotti builds upon data acquired at the lab showing network I/O intensive application can sustain a good quality of service while achieving a 8X energy reduction by spreading differently the traffic on multiple cores and tuning frequency appropriately. The project aims at building an energy-aware data center load-balancer to reduce energy waste.
Therefore, expect a new PhD and post-doc position to open soon! The post-doc one is already open, just consider it can be extended 😉
You can use mine as you wish, I tried to find the original authors and the appropriate license whenever I could. Don’t hesitate to send me your own.
NAND SSD (inspired from https://commons.wikimedia.org/wiki/File:NAND-ssd.svg, CC )RAM Module ( inspired from https://fr.m.wikibooks.org/wiki/Fichier:Ram-module.svg CC)CPU (absed on https://commons.wikimedia.org/wiki/File:Abstract_i7_CPU_icon.svg, CC)DPI (unsure but I think it’s my own. Anyway it’s standard)Fast (own)GPU (own)IPSEC (unsure)Load Balancer (unsure)Monitoring, monitor, measurements (unsure)Mellanox NIC (not SVG, Mellanox)100G NIC (inspired from the above, consider my own I guess)Router (unsure, but this is quite sandard…)VLAN (own)
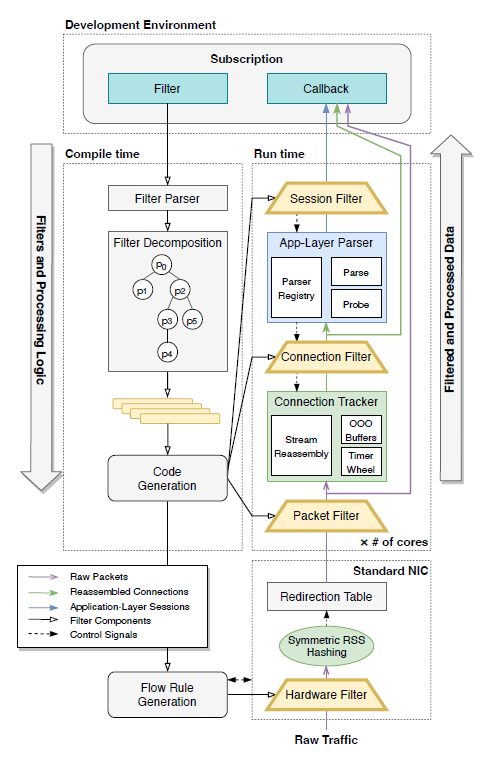
I’m pleased to announce Retina has been accepted to appear at SIGCOMM at the end of the month ! It is the result of a pleasant collaboration with Gerry Wan, Fengchen Gong and Zakir Durumeric from Stanford.
Retina enables high-speed network forensics by building a binary tailored to a specific experiment written in Rust. It provides convenient filtering capabilities to easily answer questions such as “Is the TLS SNI really random?” or “How many TLS handshake are destined to Netflix?”. Tested at up to 160Gbps with a commodity server on a Stanford traffic TAP, it supports 5-100x higher traffic rates than standard “bloatware” IDSes.
paper ; github ; the video will follow after SIGCOMM
In the Linux kernel, Block I/O request are asynchronous. It means that when you call submit_bio(READ/WRITE, bio); or generic_make_request(…), the function will (most probably) return directly, and of course, the read is not done. So after calling bio_submit(READ…); you absolutely cannot read the content of a page added by bio_add_page().
So, how to know when it is finished? You have to use bio->bi_end_io pointer function. You have to set this pointer to a function which will be called when the read has been done.
[code lang=”c”]void myReadIsFinished(struct bio* bio, int error) {
//Read is finished, do something with the bio content
}
When implementing a device driver or a MD device which can receive Block I/O (struct bio in the kernel), you can receive BIO of nearly any size, with any number of segments (segments are discontinued parts of a common buffer, defined in a bio request). You may want to limit :
– The number of segments you can receive with
[code lang=”c”]blk_queue_max_segments(queue, X);[/code]
Where X is the number of segments per struct bio
– The maximal size of the request :
[code lang=”c”]blk_queue_max_hw_sectors(queue, Y);[/code]
Where Y is the maximal size in sectors
For a md device, the queue can be recovered with mddev->queue
The combination of the two allows to limit ensure that all bio request have always maximum X segments for a maximal size of Y sectors.
It is used in raid0 with Y=mddev->chunk_sectors to ensure that no request is bigger than one chunk, so any request cross at most one chunk boundary. And with X=1, it allows to use the bio_split function to split a request which would span on the two sides of a chunk boundary.
If you’ve got your mails under a text format in a folder (like the unix Maildir) you can use this command to extract the e-mails with a 550 return error.
The first command in the pipe, cat, send all files content to the next command in the pipe : grep. Grep is removing everything except what is an adress, and only if it is followed by “host * said * 55[0-9] ” where * can be everything and [0-9] is a number between 0 and 9. We also use the –text parameter because some mails could contain binary data.
As grep give you the mail separated by new line, and an sql command takes a list of strings separated by comma, you can copy the list in gedit or notepad++ and use search->replace to change them in the format ‘mail1’, ‘mail2’, … You have to put “(.*)” in the search field, “‘\1’,” in the replace by field, and select “regular expression”. You then place the result in the parenthesis after IN, in SQL command below :
UPDATE contact SET mail='' WHERE mail IN ('bad@hotmail.com', 'error@mail.com')